Posts tagged #Direct Query

Power BI Architecture Choices for Azure Databricks (w/ Liping Huang)

LIVESTREAM DATE/TIME 📅

October 16th 2026 - 9:30 AM (Pacific Time)

DESCRIPTION 📄

Power BI gives you four main ways to report on data that lives in Azure Databricks: Direct Lake on OneLake, Direct Lake over mirrored Unity Catalog tables, DirectQuery against a Databricks SQL warehouse, and a composite model with import aggregations. Liping Huang wrote Microsoft's new white paper benchmarking all four side by side, and joins me to walk through the results.

The test runs the same TPC-DS data at roughly 26 million, 260 million and 2.6 billion rows, across cold, warm and hot cache, three filter scenarios and a 20-user load test. No pattern wins everywhere. Direct Lake holds up best for the warm and hot cache reports people open every day, queries that hit an aggregation table stay under 100ms at every volume, DirectQuery catches up (and sometimes wins) at 2.6 billion rows on an X-Large warehouse, and mirrored Unity Catalog tables slow down badly as the data grows.

GUEST BIO (NAME HERE) 👤

Liping Huang is the CEO of Data Leaps and a Data & AI Architect, blogger, YouTuber, keynote speaker and user group organizer (ex-Microsoft, ex-Databricks). Liping works with Tabular Editor as Field CTO for APAC and is passionate about helping Power BI users build better semantic models faster, creating content about Tabular Editor, Power BI, Fabric and Databricks on the Data Leaps YouTube channel and at dataleaps.co.uk.

RELATED CONTENT 🔗

White Paper (PDF)
White Paper Announcement
Data Leaps
Data Leaps YouTube
Liping's LinkedIn

(Livestream Replay) Power BI Storage Modes in Microsoft Fabric - with Phil Seamark

DESCRIPTION 📄

A review of semantic model storage modes available today in Microsoft Fabric. In particular, let's look at the new Direct Lake storage mode and help understand how this compares with Import and Direct Query, and when you might use each.

GUEST BIO 👤

Phil works for Microsoft on the Fabric Customer Advisory Team (CAT) as a DAX and Data Modelling specialist.

As part of this role, he helps global enterprise customers to optimize and tune large data models to perform their best under heavy load.

Phil has over 30 years of experience in I.T. with most of that time building solutions in business intelligence and advanced analytics.

(Livestream Replay) Why OneLake is a BIG DEAL in Microsoft Fabric - with Pawel Potasinski)

DESCRIPTION 📄

One of the key pillars of Microsoft Fabric is that it’s lake centric and open. At the core of this pillar there’s OneLake - a single, unified storage system for all your data. In this conversation Pawel and Reid will discuss and *** demo *** the benefits of OneLake for data professionals and organizations working with Fabric.

GUEST BIO 👤

Member of the Microsoft Fabric Customer Advisory Team (CAT), focused on community management and engagements. In his professional career Pawel has always been associated with data engineering and analytics (SQL, BI, Big Data). Founder of the Polish SQL Server Users Group (PLSSUG), today known as Data Community Poland. Regular speaker at conferences, community events and user groups. Former Microsoft Most Valuable Professional (MVP).

RELATED CONTENT 🔗

LinkedIn
OneLake documentation
Fabric blog
Fabric community
Fabric ideas
Fabric readiness repository

Posted on November 10, 2023 and filed under Livestreams, Fabric.

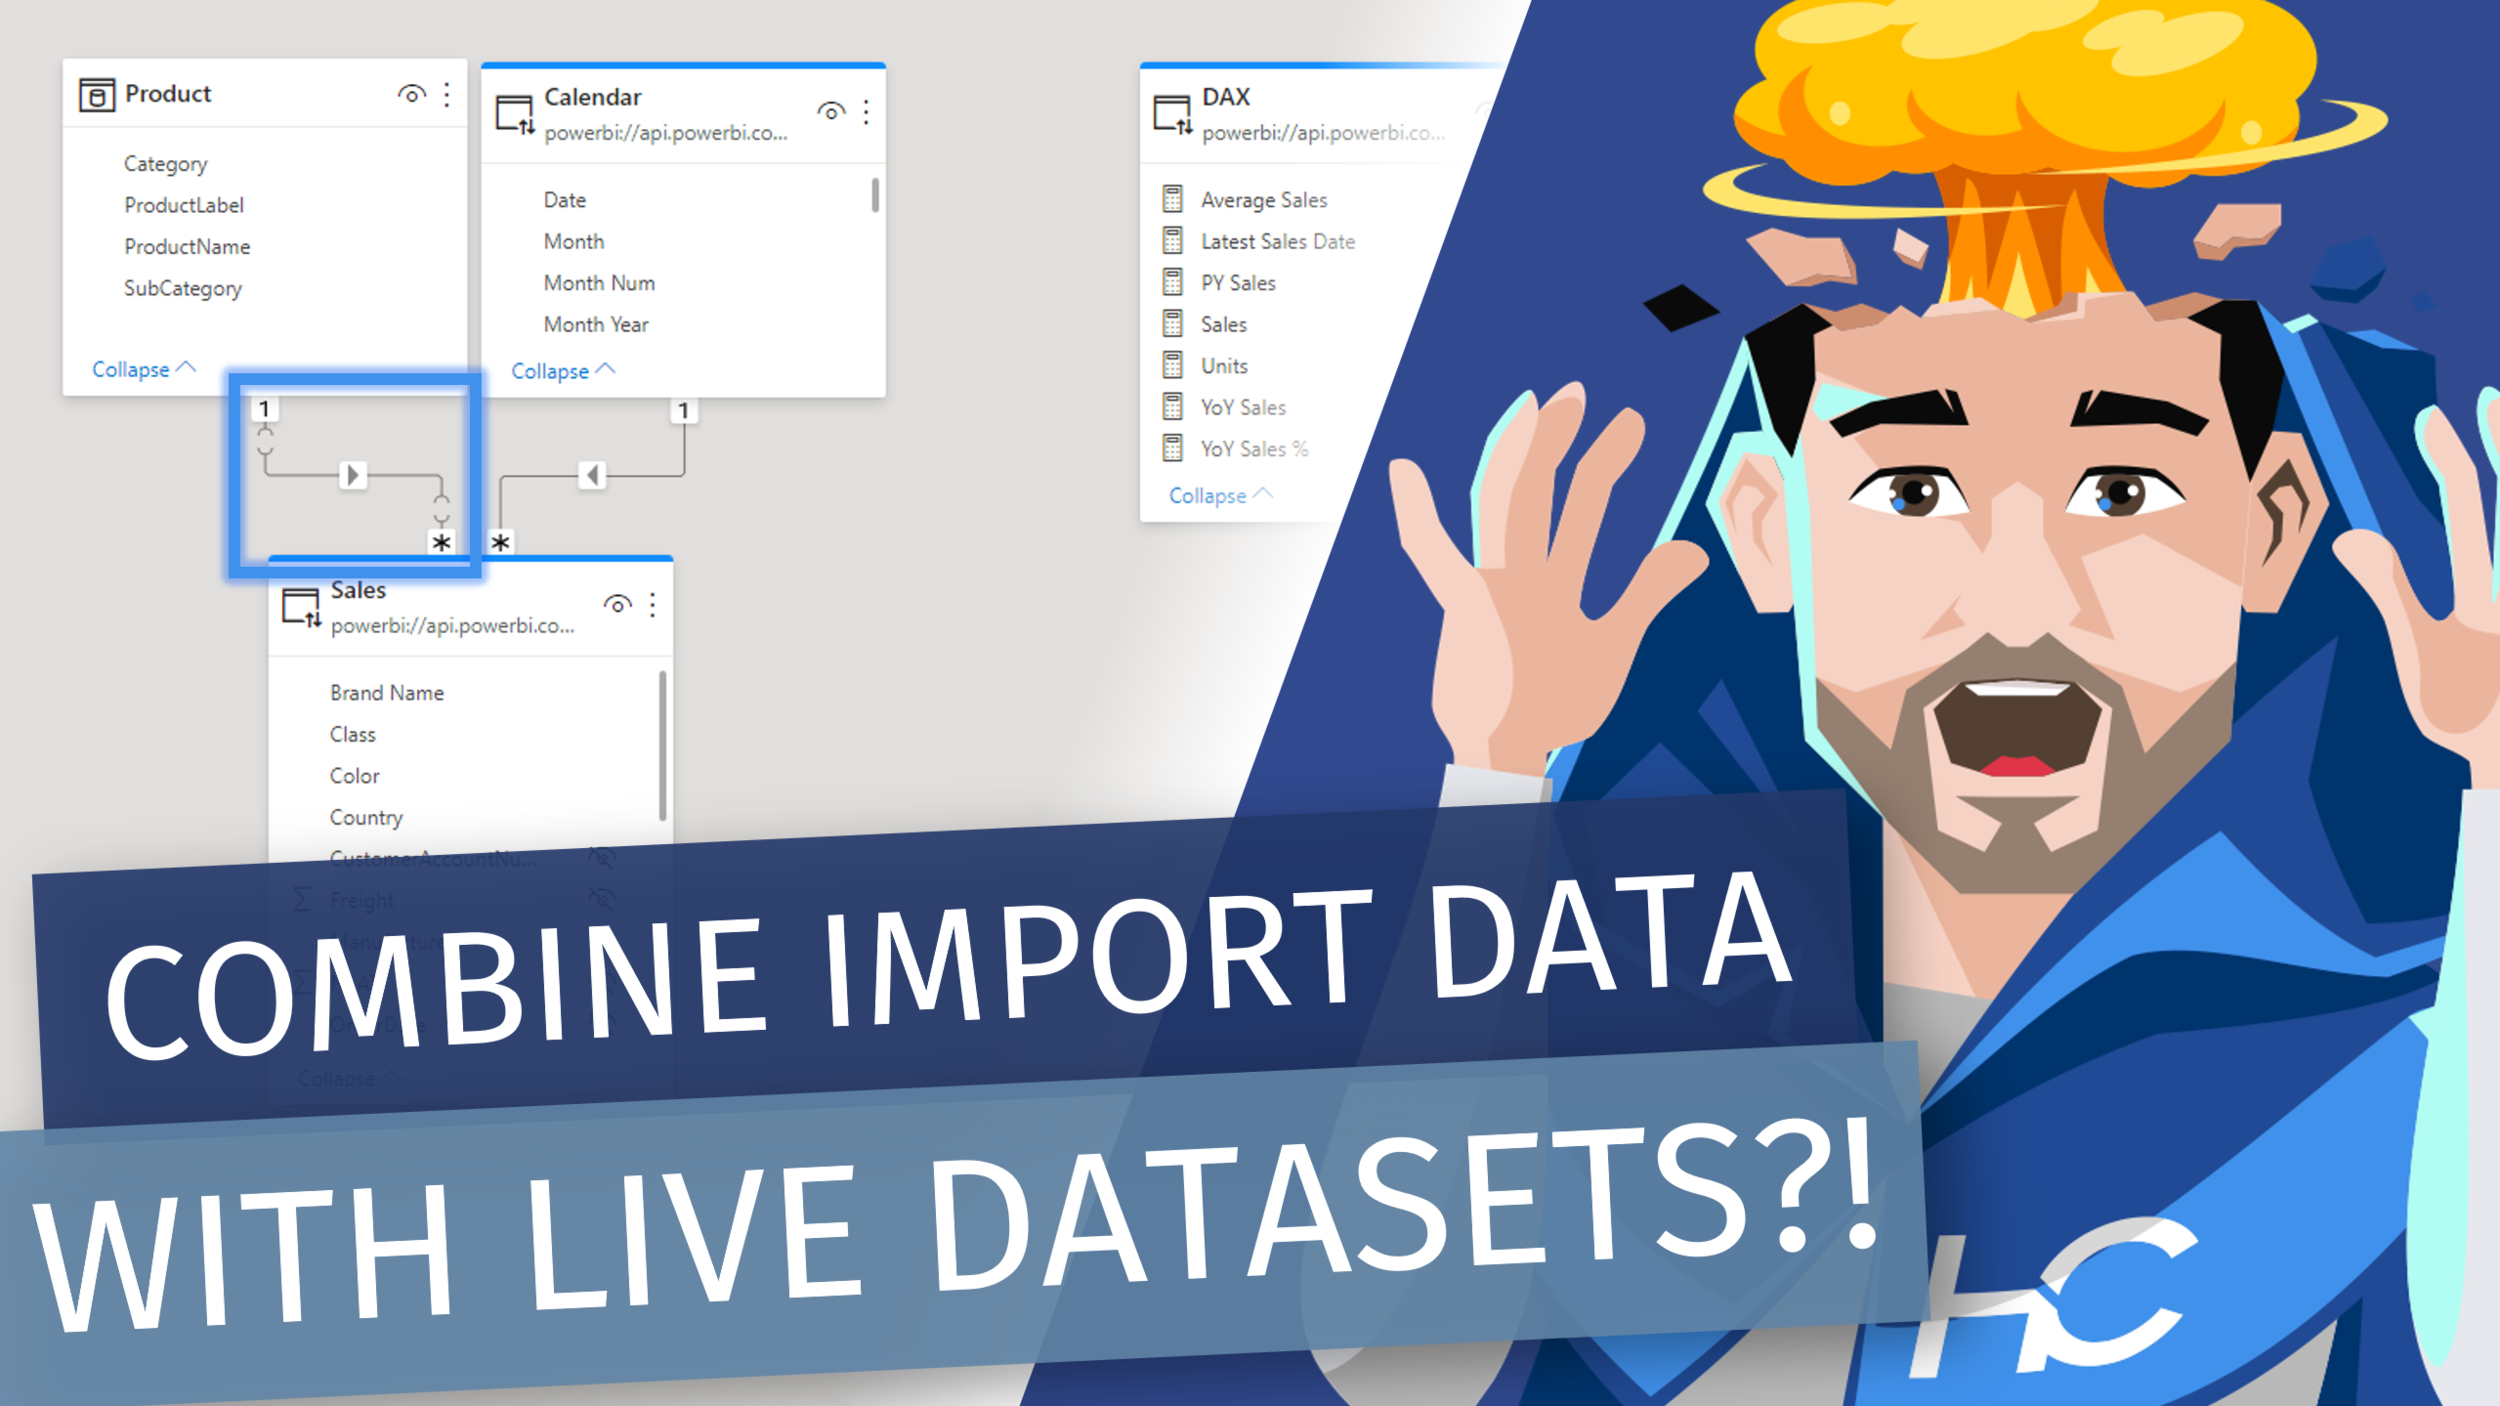
Creating a Composite Model Against a Power BI Dataset

Video by: Reid Havens

Learn how to create a composite model against a Power BI dataset, also known as (DirectQuery for Power BI datasets and Azure Analysis Services) or DQFPBIDAAS for short. 😅

Composite Models against a Power BI Dataset allows you to import tables from other data sources and combine it with your Power BI dataset.

RELATED CONTENT 🔗

Splitting a Report & Model
DirectQuery for Power BI datasets and Azure Analysis Services